标签:int htm range format url .text bre request code
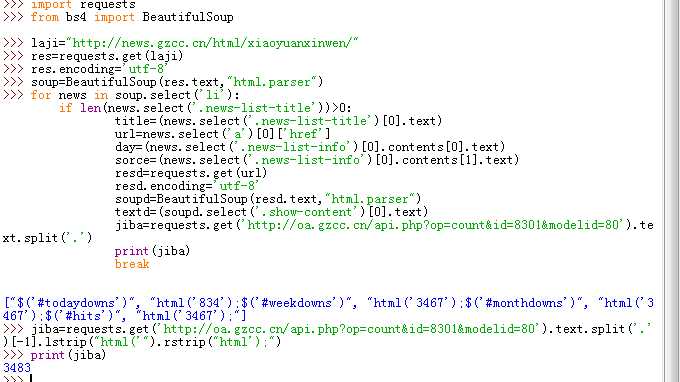
获取单条新闻的#标题#链接#时间#来源#内容 #点击次数,并包装成一个函数。
>>> import requests
>>> from bs4 import BeautifulSoup
>>> laji="http://news.gzcc.cn/html/xiaoyuanxinwen/"
>>> res=requests.get(laji)
>>> res.encoding=‘utf-8‘
>>> soup=BeautifulSoup(res.text,"html.parser")
for news in soup.select(‘li‘):
    if len(news.select(‘.news-list-title‘))>0:
        title=(news.select(‘.news-list-title‘)[0].text)
        url=news.select(‘a‘)[0][‘href‘]
        day=(news.select(‘.news-list-info‘)[0].contents[0].text)
        sorce=(news.select(‘.news-list-info‘)[0].contents[1].text)
        resd=requests.get(url)
        resd.encoding=‘utf-8‘
        soupd=BeautifulSoup(resd.text,"html.parser")
        textd=(soupd.select(‘.show-content‘)[0].text)
        jiba=requests.get(‘http://oa.gzcc.cn/api.php?op=count&id=8301&modelid=80‘).text.split(‘.‘)[-1].lstrip("html(‘").rstrip("html‘);")
        print(jiba)
        break
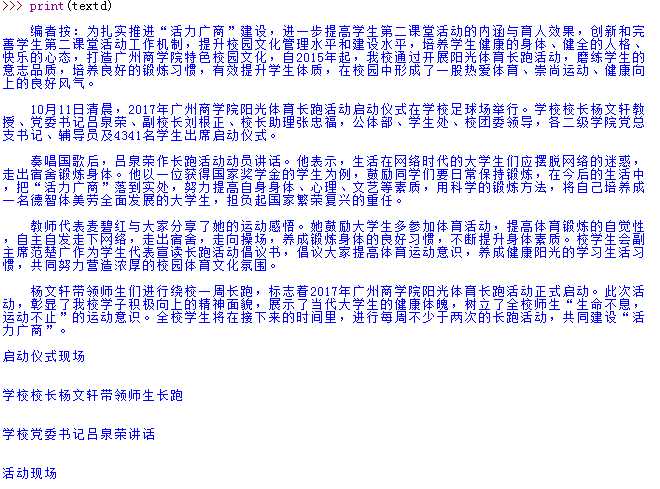
获取一个新闻列表页的所有新闻的上述详情,并包装成一个函数。
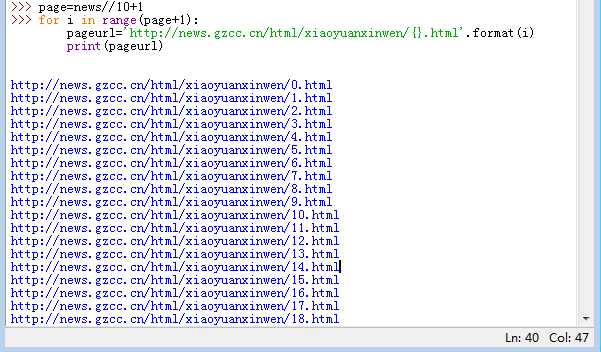
获取所有新闻列表页的网址
>>> import requests
>>> from bs4 import BeautifulSoup
>>> gzccurl=‘http://news.gzcc.cn/html/xiaoyuanxinwen/‘
>>> res= requests.get(gzccurl)
>>> res.encoding=‘utf-8‘
>>> soup = BeautifulSoup(res.text,"html.parser")
>>> news=int(soup.select(‘.a1‘)[0].text.rstrip(‘条‘))
>>> page=news//10+1
>>> for i in range(page+1):
    pageurl=‘http://news.gzcc.cn/html/xiaoyuanxinwen/{}.html‘.format(i)
    print(pageurl)
标签:int htm range format url .text bre request code
原文地址:http://www.cnblogs.com/wadee/p/7655346.html
