标签:直方图 gecko 分布式 rip 处理 res app find The
网址:http://www.weather.com.cn/textFC/hb.shtml
解析:BeautifulSoup4
爬取所有城市的最低天气
import requests
from bs4 import BeautifulSoup
import html5lib

def parse_page(url):
    headers = {
        ‘User-Agent‘: ‘Mozilla/5.0 (Windows NT 6.1; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/64.0.3282.140 Safari/537.36‘,
    }
    response = requests.get(url)
    text = response.content.decode(‘utf-8‘)
    # 需要用到html5lib解析器,去补全html标签
    soup = BeautifulSoup(text,‘html5lib‘)
    conMidtab = soup.find(‘div‘,class_=‘conMidtab‘)
    tables = conMidtab.find_all(‘table‘)
    for table in tables:
        trs = table.find_all(‘tr‘)[2:]
        for index,tr in enumerate(trs):
            tds = tr.find_all(‘td‘)
            city_td = tds[0]
            if index == 0:
                city_td = tds[1]
            city = list(city_td.stripped_strings)[0]
            temp_td = tds[-2]
            temp = list(temp_td.stripped_strings)[0]
            print({‘city‘:city,‘temp‘:temp})

def main():
    url_list = [
        ‘http://www.weather.com.cn/textFC/hb.shtml‘,
        ‘http://www.weather.com.cn/textFC/db.shtml‘,
        ‘http://www.weather.com.cn/textFC/hd.shtml‘,
        ‘http://www.weather.com.cn/textFC/hz.shtml‘,
        ‘http://www.weather.com.cn/textFC/hn.shtml‘,
        ‘http://www.weather.com.cn/textFC/xb.shtml‘,
        ‘http://www.weather.com.cn/textFC/xn.shtml‘,
        ‘http://www.weather.com.cn/textFC/gat.shtml‘,
    ]
    for url in url_list:
        parse_page(url)

if __name__ == ‘__main__‘:
    main()
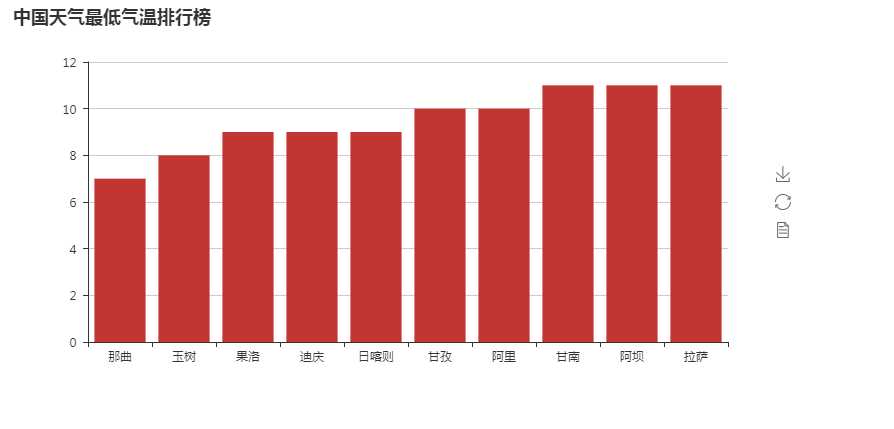
对爬取的数据进行可视化处理
代码:
import requests
from bs4 import BeautifulSoup
import html5lib
from pyecharts import Bar

ALL_DATA = []

def parse_page(url):
    headers = {
        ‘User-Agent‘: ‘Mozilla/5.0 (Windows NT 6.1; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/64.0.3282.140 Safari/537.36‘,
    }
    response = requests.get(url)
    text = response.content.decode(‘utf-8‘)
    # 需要用到html5lib解析器,去补全html标签
    soup = BeautifulSoup(text,‘html5lib‘)
    conMidtab = soup.find(‘div‘,class_=‘conMidtab‘)
    tables = conMidtab.find_all(‘table‘)
    for table in tables:
        trs = table.find_all(‘tr‘)[2:]
        for index,tr in enumerate(trs):
            tds = tr.find_all(‘td‘)
            city_td = tds[0]
            if index == 0:
                city_td = tds[1]
            city = list(city_td.stripped_strings)[0]
            temp_td = tds[-2]
            temp = list(temp_td.stripped_strings)[0]
            # print({‘city‘:city,‘temp‘:int(temp)})
            ALL_DATA.append({‘city‘:city,‘temp‘:int(temp)})


def main():
    url_list = [
        ‘http://www.weather.com.cn/textFC/hb.shtml‘,
        ‘http://www.weather.com.cn/textFC/db.shtml‘,
        ‘http://www.weather.com.cn/textFC/hd.shtml‘,
        ‘http://www.weather.com.cn/textFC/hz.shtml‘,
        ‘http://www.weather.com.cn/textFC/hn.shtml‘,
        ‘http://www.weather.com.cn/textFC/xb.shtml‘,
        ‘http://www.weather.com.cn/textFC/xn.shtml‘,
        ‘http://www.weather.com.cn/textFC/gat.shtml‘,
    ]
    for url in url_list:
        parse_page(url)
    #按天气最低进行排序,并只取10个
    ALL_DATA.sort(key=lambda data:data[‘temp‘])
    data = ALL_DATA[0:10]
    #分别取出所有城市和温度
    cities = list(map(lambda x:x[‘city‘],data))
    temps = list(map(lambda x:x[‘temp‘],data))

    chart = Bar("中国天气最低气温排行榜")
    chart.add(‘‘,cities,temps)
    chart.render(‘temperature.html‘)

if __name__ == ‘__main__‘:
    main()
结果:
标签:直方图 gecko 分布式 rip 处理 res app find The
原文地址:https://www.cnblogs.com/derek1184405959/p/9403808.html
